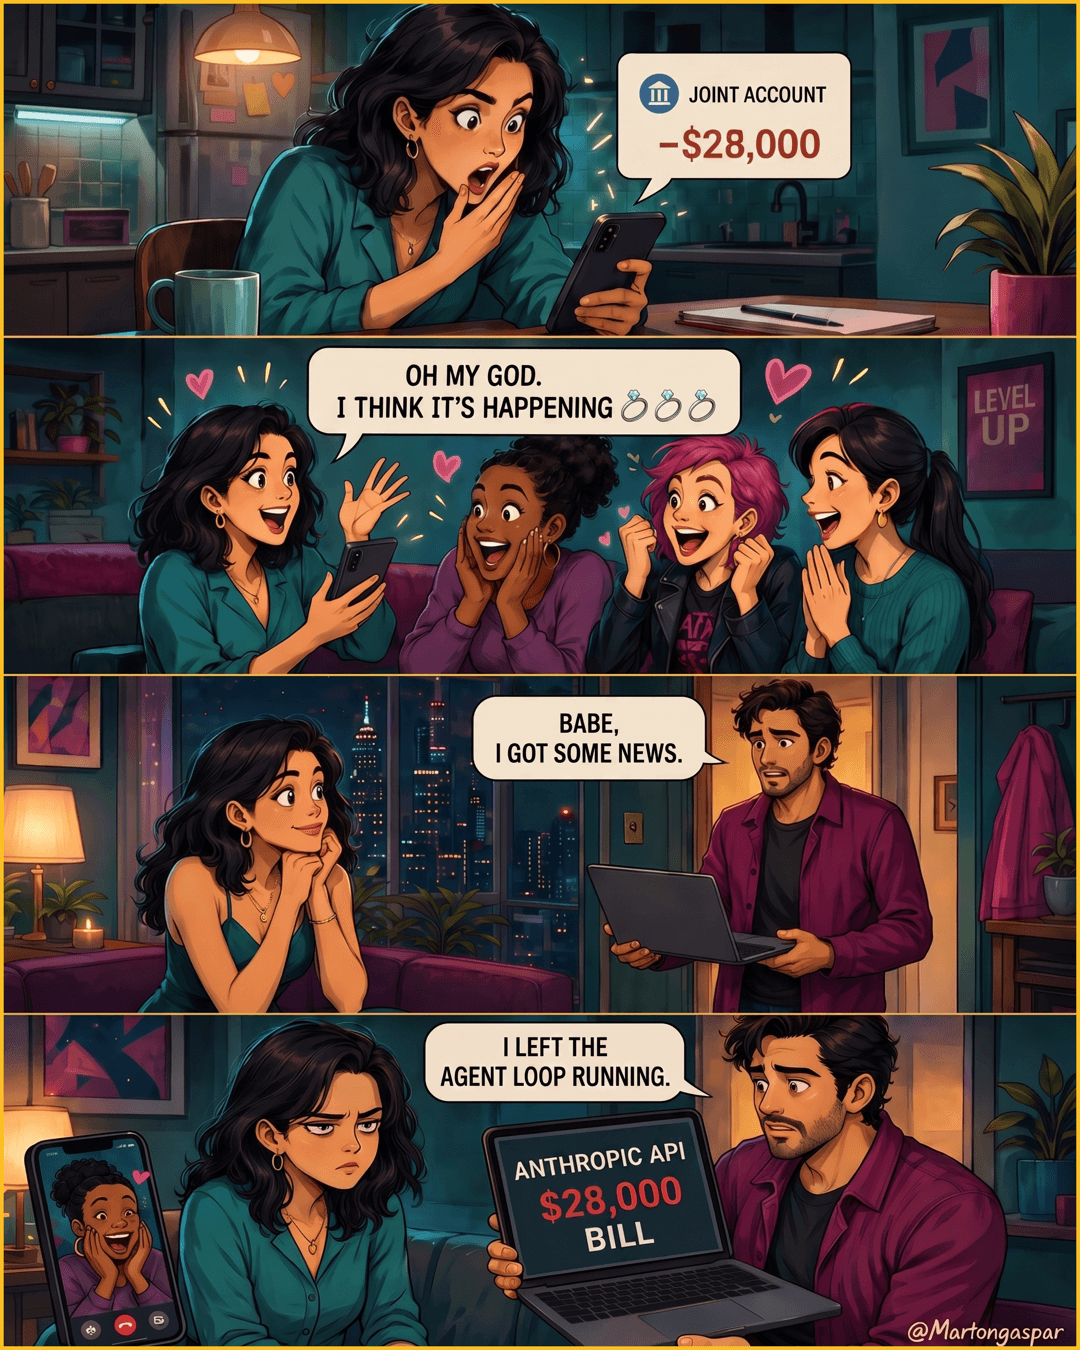
The $28,000 bill wasn't an AI problem. It was a missing line in someone's spec.
The comic that goes with this piece is a joke. A woman sees minus $28,000 on the joint account and tells her friends she thinks a proposal is coming. Then her partner walks in with his laptop and the real news: he left the agent loop running. Nobody in the comic is real. The missing line is.
When product managers write specs for agents, most of the words go on what to build. Far fewer go on when to stop. That second part used to be something a person handled along the way, without anyone writing it down. With an agent, nobody handles it unless the spec says so. This piece covers the line that tends to be missing, why the call behind it is a product call, and a quick way to check your own specs.
Where the $28,000 figure comes from
The number needs its context. It was reported from an early Microsoft usage tracker covering 350 of its 223,000 staff. The median spend was $300 over 28 days. One person reached $28,000.
That spread is variability, not proof of waste. From the tracker alone, you can't tell whether the $28,000 of work was worth it. And that is the point. Without a written finish line, the people inside the work can't say either.
A figure like this gets passed around as a cost scare. For a product manager, it is a spec question.
Agents move product judgement earlier
The common fear is that agents take the product manager's judgement off the table. The machine does the work, so what is left to decide?
A better reading: the judgement is still there. It just has to happen sooner. When you hand work to a person, the handover feels human and so does the execution. The person checks in, notices when something is going sideways, and asks whether another pass is worth it.
When you hand work to an agent, the handover still feels human. The execution is software. You write one instruction, and it turns into many paid steps. A person asks if another run is still worth the cost. An agent doesn't. Not unless you wrote it in.
The call you used to make halfway through now has to be made before the run starts.
Your spec is now a cost control
The old default treated a spec as a description of what to build. If it was vague, you paid in a rework cycle. The team built the wrong thing, you talked, they built it again. Painful, but the cost was mostly time.
With agents, a vague brief costs money every run. Each loop, retry and extra pass is a line on a bill. So the spec now does a second job. It tells the agent what to make, and it tells the agent when making more stops being worth it.
Most specs I see set one finish line. Agents need two.
Finish line one: the result is good enough
The first finish line answers a familiar question: what does done look like? Most specs have some version of it already.
Two lines carry it. The outcome: the acceptance bar, written before the run. The context: what makes hitting that bar worth anything, so the agent, and whoever reviews its work, knows why the bar sits where it does.
The trap is writing the bar after the run. Once you've seen the output, it is very easy to move the bar to meet it.
Decide what good enough means before the meter starts.
Finish line two: more work is no longer worth the cost
The second finish line is the one that tends to be missing. It answers a different question: at what point does another run stop paying for itself?
Two lines carry this one too. Decision rights: what the agent may call, retry or spend without asking. Review: when it stops, escalates or hands the work back to you.
Without those two lines, an agent that hasn't reached finish line one simply keeps going. It has no sense that the fifth attempt is worth less than the first. That judgement has to be written down, because the agent won't bring it.
The first finish line tells the agent when it has succeeded. The second tells it when to stop trying.
Why finance and platform can't write this line for you
The tempting move is to hand the cost problem to someone else. Finance sets the budget. Platform enforces the limits. Both matter, and both are blunt tools.
Neither can say what good enough means. A budget cap stops spending at a number. It doesn't know whether the work was nearly right or nowhere close. A usage limit stops the calls. It doesn't know which calls mattered.
Only the person who owns the outcome can say when more work stops being worth it for this piece of work. That call has always been yours. What changed is when you make it.
Count the lines in your last agent spec
Here is the check. Open the last agent spec your team wrote. Count the lines about what to build. Then count the lines about when another run stops being worth it.
If the second number is low, or zero, you've found the gap. It isn't a failing of whoever wrote the spec. The old format never needed that section, because a person filled it in on the fly. The gap only shows up once you start counting.
Then write the four lines: outcome and context for finish line one, decision rights and review for finish line two.
Product judgement, moved to the front
The $28,000 story reads like a story about AI costs. Underneath, it is a story about where product judgement sits in the work.
Deciding what good enough means, and when more effort stops paying off, was always part of the job. With a team of people, you could make that call along the way. With agents, you make it up front, in writing, or it doesn't get made at all.
Moving the call earlier is why the spec matters more now, not less. The work moved to the machine. The call moved earlier. It is still yours.
Download the one-page version and keep it open when you write your next agent spec.